
AVEC 2018: Pushing the Boundaries of Mental Health and Cross-Cultural Affect Recognition
AVEC 2018 Workshop and Challenge: Bipolar Disorder and Cross-Cultural Affect Recognition
The AVEC 2018 workshop introduces three standardized sub-challenges for automatic audiovisual analysis: Bipolar Disorder (BDS), Cross-cultural Emotion (CES), and Gold-standard Emotion generation (GES). It establishes a robust benchmark using the Concordance Correlation Coefficient (CCC) and Unweighted Average Recall (UAR) to evaluate multimodal machine learning methods.
TL;DR
The 8th Audio/Visual Emotion Challenge (AVEC 2018) marks a significant shift in affective computing by introducing the first-ever competition for Bipolar Disorder classification. Beyond clinical health, it tackles the "in-the-wild" challenge of cross-cultural emotion recognition (German vs. Hungarian) and the theoretical problem of generating a unified "gold-standard" from subjective human ratings.
Background: Why AVEC 2018 Matters
Affective computing has long struggled with "lab-grown" data that doesn't survive contact with reality. AVEC 2018 bridges this gap by focusing on:
- Clinical Utility: Moving from general depression to the specific manic/hypomanic phases of Bipolar Disorder.
- Cultural Robustness: Testing if an AI trained on one culture (German) can understand another (Hungarian).
- Label Integrity: Developing math-driven ways to reconcile the fact that different human annotators rarely agree on the exact timing or intensity of an emotion.
Methodology: The Core Architecture
The organizers provided a multi-layered baseline architecture incorporating supervised, semi-supervised, and unsupervised feature extraction.
1. The Deep Spectrum Approach (Unsupervised)
A standout novelty is the use of Deep Spectrum features. Instead of manually defining "pitch" or "energy," speech is converted into mel-spectrogram images. These images are fed into a pre-trained AlexNet (originally for image recognition), using the activations from the fc7 layer as feature vectors. This treats audio as a visual pattern-recognition problem.
2. Time-Dependent Modeling
For emotion recognition, the baseline uses a 2-layer LSTM-RNN. This is critical because emotions are not static; the "valence" (positivity/negativity) of a sentence depends on the temporal context of what was said seconds before.
Experiments and Results
The results highlight the difficulty of "in-the-wild" cross-cultural tasks compared to controlled environments.
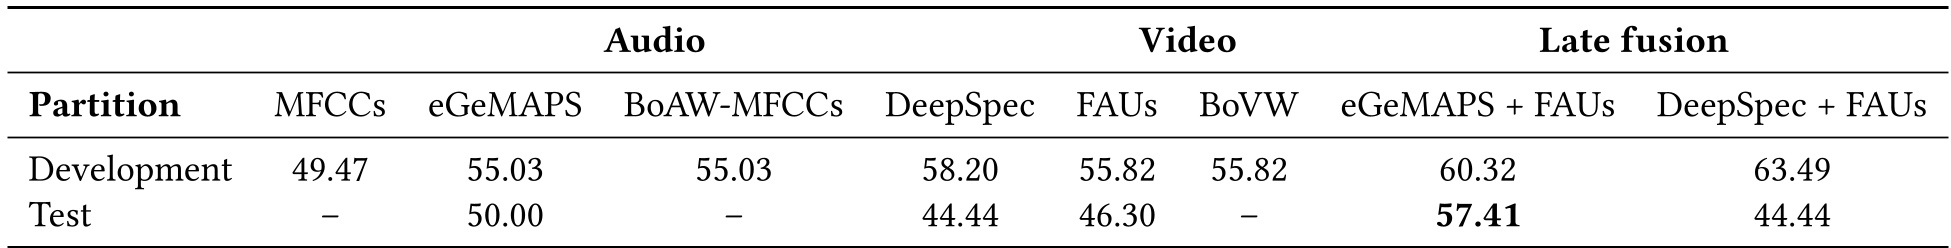
- Bipolar Disorder (BDS): The unsupervised Deep Spectrum features (58.20% UAR) outperformed traditional expert-knowledge features (eGeMAPS) on the development set, suggesting that deep learning can find "hidden" biomarkers of mania that human-defined features miss.
- Cross-Cultural (CES): While Arousal and Valence yielded reasonable Concordance Correlation Coefficients (CCC), "Liking" was poorly predicted. This suggests that "liking" something is more culture-specific or linguistically driven than the universal physical signals of "excitement" (arousal).
Performance Summary Table
Below is a snippet of the baseline performance across modalities:
Critical Insights & Future Outlook
The "Reaction Time" Problem: The GES (Gold-standard) task highlights a persistent issue: humans have a physical delay (reaction time) when annotating video. The AVEC 2018 baseline compensates for this by shifting labels in time to maximize correlation—a "calibration" step that is now essential for any time-continuous affect model.
Limitations: The primary limitation noted is the omission of linguistic transcriptions in the baseline. In real-world scenarios, what is said is often as important as how it is said.
Takeaway for Researchers
If you are building AI for healthcare or social robotics, the lesson of AVEC 2018 is clear: unsupervised feature learning (like Deep Spectrum) is closing the gap with expert-tuned features, and multimodal fusion (combining video and audio) is no longer optional—it is the prerequisite for dealing with human diversity and cultural nuances.