
Bayesian Learning in Social Networks: Why We Eventually Follow the Crowd
Bayesian Learning in Social Networks
The paper investigates Bayesian social learning within a structured network, focusing on how agents simultaneously and repeatedly choose actions based on private signals and observations of neighbors. It establishes that in any connected network, agents will eventually reach a state of uniform action through the "Imitation Principle" and "Welfare-Improvement Principle," regardless of initial diversity.
TL;DR
Why do fashions, fads, and social movements eventually consume entire populations? This classic paper by Douglas Gale and Shachar Kariv moves beyond simple "follow-the-leader" models to show that in any connected social network, rational agents will eventually converge to identical behavior. By combining Bayesian inference with network theory, the authors prove that the ability to observe and imitate neighbors inevitably leads to a "herd," even when agents start with vastly different private information.
Background: Beyond the Linear Queue
Standard models of social learning—like those explaining why people choose the busier of two neighboring restaurants—usually assume a sequential queue (Agent 1 goes, then Agent 2 observes 1 and goes, etc.). This paper introduces the Social Network Model (SNM), which is far more realistic:
- Simultaneous Play: Everyone acts at the same time and revises their choices in every period.
- Local Visibility: You only see what your "friends" (neighbors) do, not the whole world.
- Perfect Recall: Agents remember the entire history of actions they've observed.
The Core Principles: Why Convergence is Inevitable
The authors identify two powerful mathematical intuitions that drive the network toward uniformity:
1. The Welfare-Improvement Principle
In a Bayesian world, more information is always better. Because agents have "Perfect Recall" and observe new actions every period, their information set is non-decreasing. Mathematically, their expected utility behaves as a submartingale, meaning it is expected to stay the same or increase over time. This implies that everyone's "success" or payoff eventually stabilizes.
2. The Imitation Principle
This is the "special sauce" of the paper. If Agent A can see Agent B, Agent A can always choose to do exactly what Agent B did in the previous round. If Agent B is doing better, Agent A will eventually pivot. In a connected network (where a path exists between any two people), this pressure to imitate flows through the entire system until everyone achieves the same long-term payoff.
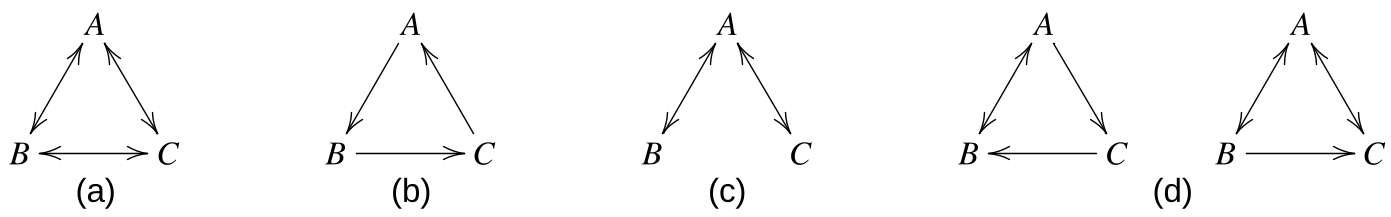 Figure 1: Different network topologies (Complete, Circle, Star) studied to see how information flows.
Methodology: The Math of the "Cutoff Rule"
The authors demonstrate that rational agents follow a cutoff rule. Imagine deciding whether to adopt a new technology (Action 1) or stay with the old (Action 0). An agent calculates the expected value of Action 1 based on their signal. If it's above a certain threshold (the cutoff), they act.
As they observe neighbors, they update their beliefs about the "hidden" state of the world, effectively shifting their cutoffs. In a two-person network, if Agent A sees Agent B choose Action 1, Agent A shifts their belief positively. If their signal was only slightly negative, they might "flip" to Action 1 in the next round.
Key Insights from Short-Run Dynamics
The paper provides fascinating simulations of 3-person networks:
- The Complete Network: Learning is lightning-fast but dangerous. If two people happen to have weak signals that point the same way, the third person joins them immediately, potentially ignoring a very strong private signal. This often leads to inefficient herds.
- The Star Network: Here, the "Central" agent acts as an information hub. Because the peripheral agents can't see each other, they rely on the center to "transmit" information. This actually slows down the process, allowing more private information to be revealed through actions over time.
- The Circle: With no common knowledge, agents make complex "inferences about inferences," leading to prolonged periods of alternating actions before finally settling.
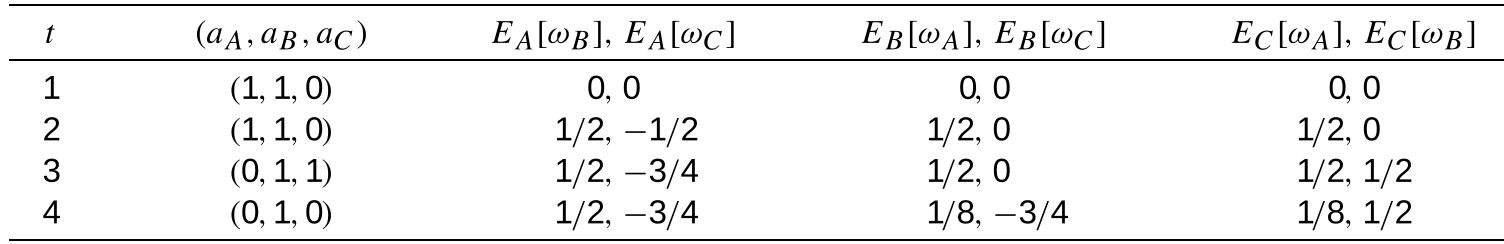 Table 1: The step-by-step evolution of beliefs and actions in a Star Network, showing how learning persists over several periods.
Critical Analysis & Conclusion
This work provides a rigorous foundation for why social groups tend toward homogeneity. However, it also highlights a paradox: Full transparency isn't always best. In a "Complete" network, we are more likely to reach a "wrong" consensus quickly. In contrast, "Incomplete" networks (like the Star or Circle) keep diversity alive longer, which can ironically lead to a more accurate long-term consensus because more private signals are "baked into" the final behavior.
Limitations: The model assumes "Individually Insignificant Agents" to ignore strategic manipulation (i.e., people acting weirdly today just to trick others tomorrow). In small, high-stakes groups, this strategic element could change the results significantly.
Takeaway: In the age of social media, our "neighborhoods" have expanded. Gale and Kariv's work suggests that as our networks become more "Complete," the speed of convergence increases, but the risk of us all being "uniformly wrong" increases along with it.