
From Big Data to Smart Data: The Strategic Evolution of Educational Analytics
Big Data, the Next Step in the Evolution of Educational Data Analysis
This paper explores the transition from traditional Data Warehousing to advanced architectures like Big Data, Smart Data, and Data Lakes within the educational sector. It proposes an integrated framework centered on Smart Data and Data Mining to enable personalized high-quality education by processing diverse student datasets from Learning Management Systems (LMS) and campus sensors.
TL;DR
As educational institutions outgrow traditional Data Warehouses, this paper argues against the "bigger is always better" Big Data hype. Instead, it proposes Smart Data as a high-value filter and Data Lakes as flexible repositories to transform raw Moodle logs and campus sensor data into actionable insights for personalized student support.
The Scalability Crisis in Campus Analytics
For years, universities used Learning Management Systems (LMS) like Moodle as simple digital silos. However, as the diversity of data grows—including multimedia logs, external links, and virtual tutorials—the traditional Data Warehouse architecture is hitting its limit. The primary pain points are:
- Veracity Loss: Massive data influx compromises the accuracy of traditional reporting.
- Processing Ceiling: Cubes generated in a data warehouse are becoming too heavy for real-time decision-making.
- Unstructured Data: Traditional SQL-based systems struggle with the "wild" data coming from social networks and IoT sensors.
Methodology: Choosing the Right Data Paradigm
The researchers analyzed three distinct paths for the evolution of the University of Las Américas (Ecuador):
- Big Data: High volume (30TB+), high velocity, but also high infrastructure cost.
- Data Lake: A storage-first approach where data is kept raw until needed. It eliminates the "costly" ETL (Extract, Transform, Load) phase but requires high-level data scientists to navigate.
- Smart Data: A strategic filter. It doesn't just store data; it extracts value using mathematical formulas to answer specific educational questions (e.g., "When is a student most likely to fail?").
Comparative Framework
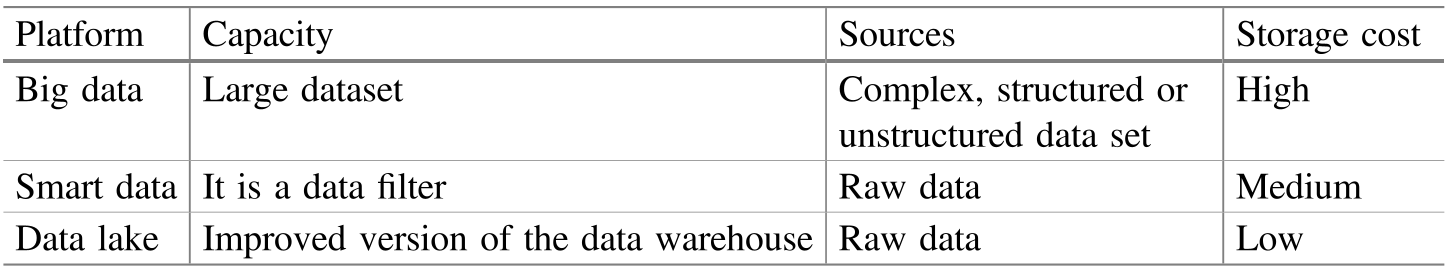
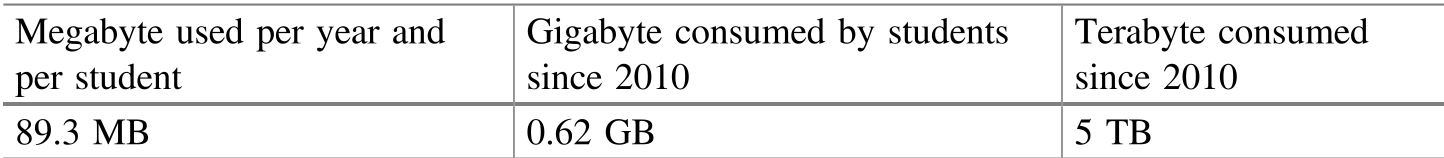
The authors conclude that for an institution where an average student generates roughly 89.3 MB per year (Total ~5TB historical), a full Big Data implementation would be "oversized." Instead, Smart Data offers a medium-cost, high-availability alternative.
The Case Study: Integrating the 360-Degree Student View
The university currently handles 8,000 students. By calculating the storage consumption per period, the authors proved that the current volume is manageable if the focus shifts from storage to intelligence.
The proposed "Next Step" involves:
- Cross-System Integration: Merging Moodle data with financial status, library trends (printing systems), and even cafeteria consumption (coffee intake during exams).
- Real-time Analysis: Moving away from end-of-period reports to daily/monthly pattern detection via Microsoft Power BI.
- Data Mining Convergence: Using search and cluster algorithms to identify "risk groups" before they fail.
Critical Insight & Conclusion
The most profound takeaway is that Smart Data is the "filter" that makes Big Data useful. In education, capturing every single mouse click (Big Data) is less important than identifying the specific sequence of clicks that leads to a learning breakthrough (Smart Data).
Limitations & Future Outlook
While the Smart Data approach reduces technical infrastructure costs, it increases Human Cost. Institutions will need highly trained data scientists rather than just database administrators. The authors are currently validating these findings using Power BI to integrate four different student activity systems, with initial results promising a much more tailored "personalized education" experience.
Final Verdict: This paper serves as a roadmap for mid-tier institutions to modernize their tech stack without the multi-million dollar price tag of typical Big Data architectures.