
SNAC: Decoding History through Archival Social Networks
Connecting Archival Collections: The Social Networks and Archival Context Project
The SNAC (Social Networks and Archival Context) project introduces a systematic framework for merging disparate archival records (EAD) into a unified biographical database using the EAC-CPF standard. It achieves state-of-the-art name disambiguation by combining Multinomial Naive Bayes classifiers with biographical metadata like existence dates.
TL;DR
The Social Networks and Archival Context (SNAC) project is a pioneering effort to bridge the gap between fragmented primary resources (letters, diaries) and the historical figures who created them. By extracting data from diverse archival finding aids and applying probabilistic name disambiguation, SNAC builds a "social graph" of history, allowing researchers to explore connections between persons, families, and organizations with unprecedented clarity.
Background: The Hidden Threads of History
For historians, primary resources are the gold standard. However, these documents are scattered across institutions like the Library of Congress and the California Digital Library. Each repository might describe the same person differently. The SNAC project aims to fix this "identity crisis" in the archives by moving away from isolated records toward a linked data ecosystem.
The Problem: When "Smith, John" isn't just "John Smith"
Existing archival metadata (Encoded Archival Description or EAD) often lacks strict authority control. The authors identified several critical pain points:
- Inconsistent Formatting: Names appear in direct or inverted orders.
- Noise: Subject subdivisions or titles are often bundled with name strings.
- Ambiguity: Thousands of records might refer to the same individual, but without a unique identifier, they remain disconnected.
Methodology: The Architecture of Identity
The SNAC workflow involves a multi-stage pipeline: extraction, matching, and presentation.
1. Extraction and Transformation
Using XSLT 2.0, the system identifies <persname>, <corpname>, and <famname> tags within EAD records. These are then converted into the EAC-CPF (Encoded Archival Context) format, which focuses specifically on the entities rather than the documents.
Note: See Figure 1 & 2 in the original paper for the internal prototype interface examples.
2. Probabilistic Disambiguation
To merge duplicate records, the team moved beyond simple "String Edit Distance" (Levenshtein Distance), which is too sensitive to word order. Instead, they used a Naive Bayes approach:
- Character Shingles (N-grams): Names are broken into 3-character sequences (e.g., "Einstein" becomes "ein", "ins", "nst"). This captures the local structure of a name regardless of its position.
- Multinomial Model: This counts the frequency of shingles, providing a more robust "fingerprint" of a name.
- The "Date Boost" Insight: Since many historical figures share names, the authors added a score booster () if the birth and death dates in the archival record matched the library authority files.
Experimental Results: The Power of Context
The study compared three primary approaches. While basic string matching (Edit Distance) performed poorly, the Multinomial Model provided a strong baseline. However, the true breakthrough came from integrating biographical dates.
| Approach | Accuracy (Top-1) | Accuracy (Top-10) |
|---|---|---|
| Edit Distance (Baseline) | 42.9% | 83.4% |
| Multinomial Model (String Only) | 60.82% | 86.71% |
| Multinomial + Date Boosting | ~84.7% | ~89.5% |
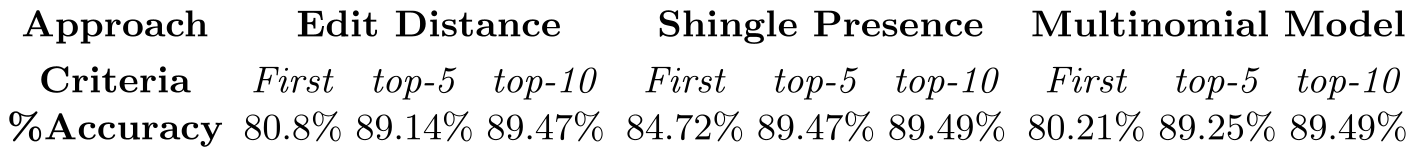 Table: Performance of different matching methods with and without biographical date boosting.
Exploring the Social Graph
The SNAC prototype doesn't just list names; it visualizes relationships. For an entity like General George S. Patton, the system displays:
- CreatorOf: Archives actually written by him.
- ReferencedIn: Documents mentioning him.
- Social Network: A graph view of correspondents, family, and professional associates.
Critical Insight & Future Outlook
The SNAC project proves that archival discovery should be entity-centric rather than collection-centric. By centering the "Person" and their social network, we can navigate history through the web of human relationships.
Limitations: The current model relies heavily on Western European languages and assumes the presence of relatively clean existence dates. Future work involving machine learning for "biographical note" parsing could further improve accuracy for records where dates are missing.
Conclusion: SNAC is a vital step toward a "Semantic Web for History," transforming how we interact with the remnants of the past.