
EDPG-Assignment: Bridging the Gap Between Continuous Policy Gradients and Discrete Crowdsourcing Tasks
An Embedding-based Deterministic Policy Gradient Model for Spatial Crowdsourcing Applications
This paper introduces EDPG-Assignment, an advanced reinforcement learning framework for spatial crowdsourcing task allocation. It utilizes an Embedding-based Deterministic Policy Gradient approach combined with Clipped Double Deep Q-Learning to maximize long-term rewards in interactive environments.
TL;DR
The paper introduces EDPG-Assignment, a Reinforcement Learning (RL) framework designed to optimize long-term rewards in spatial crowdsourcing. By combining Matrix Factorization (embedding) with a Deterministic Policy Gradient (DPG) and a k-Nearest Neighbor (k-NN) search, the authors solve the "large discrete action space" problem, allowing smooth continuous optimization to function within the discrete reality of task assignment.
Background & Motivation: The Static Trap
Most spatial crowdsourcing platforms (like Uber or TaskRabbit) treat task assignment as a static, one-off matching problem. This is a "greedy" strategy that ignores the long-term feedback loop. For instance, assigning a worker a task that is too far away might increase immediate profit but cause the worker to log off early, hurting future platform availability.
While Reinforcement Learning is the natural tool for maximizing long-term rewards, it faces two "Curse of Dimensionality" hurdles in crowdsourcing:
- Large Action Spaces: In a city-scale system, there are thousands of workers and tasks. Computing Q-values for every possible pair is computationally prohibitive.
- Discrete vs. Continuous: Standard DPG models (like DDPG) work in continuous spaces (e.g., controlling a robot's joint torque). Crowdsourcing tasks are discrete—you can't assign "half of task A and half of task B."
Methodology: The "Embed-Search-Refine" Pipeline
The core innovation of EDPG-Assignment lies in its three-stage approach to bridging the continuous-discrete divide.
1. Matrix Factorization for Action Embedding
The authors use Alternating Least Squares (ALS) to decompose the worker-task interaction matrix into latent factor vectors (embeddings). These embeddings capture the "physical intuition" of the task—location, worker preferences, and historical success—mapping discrete IDs into a dense -dimensional space.
2. Policy-Based Actor Learning
Instead of selecting a specific task ID, the Actor Network outputs a "proto-action" in the continuous embedding space. This represents the ideal task characteristics the system should look for based on the current state.
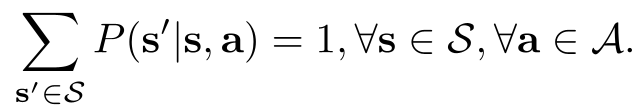 (Formula 1: Defining the probability of state transitions in the CMDP)
3. Neighbor-based Discrete Mapping
Since a "proto-action" can't be executed directly, the system uses a K-D-Tree to find the nearest real tasks in the embedding space. The Critic Network then evaluates these candidates and selects the one with the highest estimated Q-value.
Stabilizing the Learner: Clipped Double Q-Learning
To prevent the "overoptimization" bias common in Actor-Critic setups, the authors incorporate Clipped Double Deep Q-Learning. By maintaining two Critic networks and taking the minimum of their outputs, the model avoids overestimating the value of specific task assignments, leading to a much more stable training process.
Experiments and Results
The model was tested on the FourSquare dataset, simulating 1,105 workers and 2,183 tasks.
- The k-Neighbor Effect: The study found that increasing (the number of candidates searched) significantly improves precision. Moving from (nearest hit) to raised precision from 0.60 to 0.635.
- Embedding Sensitivity: The precision is also robust to the number of embeddings, showing that even with a relatively small latent space, the structural relationships between tasks are well-captured.
 (Table V: Impact of k-value on Algorithm Precision)
Critical Insight & Future Outlook
EDPG-Assignment effectively treats task assignment as a "Search and Recommendation" problem within an RL framework. By moving the heavy lifting of action selection into the embedding space, it circumvents the complexity of traditional Q-learning.
Limitations: The model assumes the embedding space (via ALS) is relatively static or pre-computed. In a hyper-dynamic environment where millions of tasks appear and disappear in seconds, the cost of updating embeddings might become a new bottleneck.
Future Work: This methodology could potentially be unified with Graph Neural Networks (GNNs) to learn better spatial-temporal embeddings, further improving the context-awareness of the task assignments.
Conclusion
This paper provides a robust solution for interactive spatial crowdsourcing. By smartly combining embedding techniques with modern DRL architectures, it proves that long-term reward optimization is not only possible but scalable for real-world urban applications.