
Deciphering the Human Face: A Deep Learning Journey into Emotion Recognition
Emotion Recognition Through Facial Gestures - A Deep Learning Approach
This paper presents a Facial Emotion Recognition (FER) system leveraging a custom Deep Convolutional Neural Network (CNN) architecture to classify seven basic emotions. Developed using the FER-2013 dataset, the proposed "Network E" achieves an absolute accuracy of 63.03% and a top-2 accuracy of 67%, significantly outperforming traditional Support Vector Machine (SVM) baselines.
TL;DR
Human emotions are rarely binary; they are a nuanced blend of signals. This research proposes a sophisticated Convolutional Neural Network (CNN) architecture designed to move beyond rigid classification. By transitioning from traditional Support Vector Machines (SVM) to a deep hierarchical CNN, the authors achieved an accuracy of 63.03% on the challenging FER-2013 dataset, providing a framework that mirrors the complexity of human perception.
The "Amalgamation" Problem
Why is emotion recognition so difficult? Unlike identifying a "cat" or a "dog," facial expressions like a "sad smile" or "surprised anger" occupy a gray area. Current SOTA models often fail because they treat emotions as mutually exclusive categories. The authors argue that since 55% of human communication is attributed to facial gestures, we need a model that doesn't just pick a label, but understands the intensity and distribution of those labels.
Methodology: From Traditional ML to Deep CNNs
The research followed a rigorous evolutionary path. Initially, the team tested Support Vector Machines (SVM), which peaked at a disappointing 46.74% accuracy. This failure highlighted that hand-crafted features or simple statistical models cannot capture the non-linear spatial hierarchies of a human face.
The Winning Architecture (Network E)
The researchers iteratively tested five architectures (A through E). The final model, Network E, succeeded by prioritizing two elements:
- Iterative Convolution Blocks: Multiple layers to capture finer edges and textural patterns.
- Massive Dense Layer: A fully connected layer with 3,072 filters allowed the model to synthesize high-level "concepts" from the raw features before the final classification.
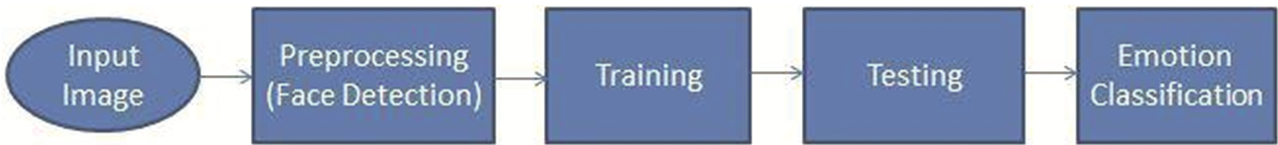 Figure 1: The dual-phase training/testing architecture utilizing the FER-2013 database.
Experiments & Quantitative Breakthroughs
The team utilized the FER-2013 dataset, consisting of 37,887 grayscale images. Preprocessing was handled by the Viola-Jones algorithm to ensure the model focused strictly on the facial bounding box.
Performance Comparison
| Model | Accuracy (%) |
|---|---|
| SVM | 46.74 |
| Network A (LeNet inspired) | 58.00 |
| Network E (Proposed) | 63.03 |
The jump from SVM to Network E represents a nearly 35% relative improvement.
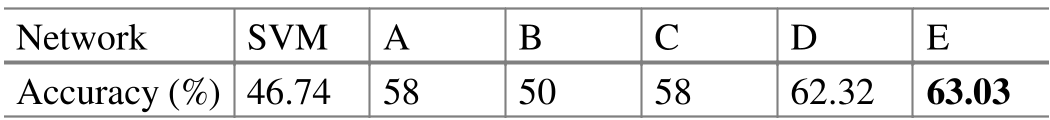 Figure 2: Performance metrics across different attempted architectures.
The Top-2 Insight
In a brilliant stroke of analysis, the authors looked at "Top-2" accuracy. If the model’s second choice was the "correct" one, the accuracy jumped to 67%. For example, in ambiguous cases where a child might look "Sad" or "Neutral," the model captured both possibilities in its probability distribution, mimicking the subjective nature of human sight.
Critical Insight & Conclusion
The core takeaway is that depth alone isn't enough. The success of "Network E" was driven by the specific expansion of the dense layer (the "thinking" part of the brain) after the feature extraction (the "seeing" part).
Limitations & Future Work
While 63% is a solid baseline for a custom CNN, the field has since moved toward Transfer Learning (using pre-trained models like ResNet) and Attention Mechanisms. The authors acknowledge that while their system is robust against age, gender, and ethnicity, a more comprehensive grid search for hyperparameters could push these boundaries even further.
This work stands as a strong physiological-to-digital bridge, proving that deep learning doesn't just recognize faces—it begins to "feel" the emotions behind the pixels.