
Collective Intelligence in Genomics: Boosting SNP Selection via Rank Aggregation
Ensemble Feature Selection using Rank Aggregation Methods for Population Genomic Data
The paper introduces an ensemble feature selection approach for Single Nucleotide Polymorphism (SNP) data by applying rank aggregation methods from social choice theory. By combining three established genetic metrics (Delta, FST, and In) via heuristic aggregation algorithms like Borda and Markov Chains, the authors achieve superior population assignment accuracy with fewer genetic markers.
Executive Summary
TL;DR: In the high-stakes world of population genetics, identifying the most "informative" genetic markers (SNPs) is crucial for everything from food traceability to forensic science. This paper moves beyond using a single statistical metric, instead employing Rank Aggregation—a technique from voting theory—to combine multiple genetic evaluations into a single, high-performance ensemble ranking.
Academic Context: This study serves as a successful bridge between Social Choice Theory and Bioinformatics. It demonstrates that ensemble feature selection can overcome the inconsistencies of traditional genetic markers like Wright's or Informativeness for Assignment (), reaching critical accuracy thresholds (95%+) significantly faster than individual methods.
The Bottleneck: High Dimensions and Drifting Metrics
In genomics, a Single Nucleotide Polymorphism (SNP) is a variation at a single position in a DNA sequence. Modern datasets contain millions of these SNPs, but only a handful are actually useful for determining an individual's population of origin. Selecting these "informative markers" is essential because:
- Cost: Genotyping millions of markers is prohibitively expensive for routine use.
- Computational Complexity: High dimensionality leads to the "curse of dimensionality," reducing the generalization power of classifiers.
Historically, researchers relied on metrics like Delta (), Wright’s , or Mutual Information (). However, the literature is contradictory—one metric might work for European pigs but fail for Asian cattle. There is no "universal winner."
Methodology: SNPs as Political Candidates
The authors' core insight is to treat the feature selection task as a voting problem. Each genetic metric (Delta, , and ) acts as a "voter" that provides its own ranked list of the most important SNPs.
1. The Rank Aggregation Heuristics
They explored two main categories of aggregation:
- Borda Methods: These assign scores based on an item's position in each list. The authors used different "means" to combine these scores: Arithmetic, Geometric, Median, and the -norm (Euclidean distance).
- Markov Chain Methods (MC1 & MC2): These treat the ranking as a state-transition problem. A transition matrix is built where the "chain" moves toward SNPs that are ranked higher by the majority of the input lists. The stationary distribution of this chain provides the final ranking.
2. Experimental Setup
The framework was tested on a massive dataset of 59,436 SNPs from 446 pigs across various breeds. The researchers used a Bayesian assignment method (Rannala and Mountain) to evaluate how well the selected SNPs could correctly identify a pig's breed.
Experimental Results: The Power of the Ensemble
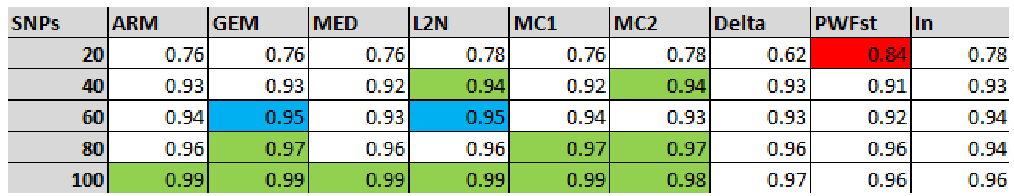
The results validated the "Ensemble" hypothesis. While traditional started strong with very small subsets (20 SNPs), it plateaued quickly.
| SNPs Selected | L2-Norm (Rank Agg) | MC2 (Rank Agg) | Wright's (Traditional) |
|---|---|---|---|
| 20 | 0.78 | 0.78 | 0.84 |
| 40 | 0.94 | 0.94 | 0.91 |
| 60 | 0.95 | 0.93 | 0.92 |
| 80 | 0.96 | 0.97 | 0.96 |
| 100 | 0.99 | 0.98 | 0.96 |
Key Observations:
- Faster Convergence: The rank aggregation methods (specifically -norm) hit the 95% accuracy threshold at just 60 SNPs.
- Stability: Ensemble methods showed more consistent growth in accuracy compared to individual metrics, which often "chatter" or stall.
- The 100-SNP Ceiling: At 100 SNPs, almost all proposed aggregation methods hit near-perfect accuracy (99%), outperforming the best traditional metric () by 3%.
Critical Analysis & Future Outlook
The beauty of this approach lies in its simplicity and agnosticism. Because it handles rankings rather than raw scores, it can combine any number of disparate metrics without needing to normalize their underlying mathematical distributions.
Limitations
- Averaging Out "Deep" Insights: By seeking consensus, rank aggregation might occasionally ignore a single metric that identifies a very rare but critical mutation.
- Unweighted Votes: The study currently treats all metrics as equal. In reality, was clearly superior for the top 20 SNPs.
Future Work
The authors suggest a Weighted Rank Aggregation model. If a specific metric shows a high "acceleration" in accuracy for the first few markers, the aggregator should give it more "voting power" in that specific range. Furthermore, incorporating the raw scores (relative distance between ranks) rather than just the ordinal positions could unlock even higher precision.
Conclusion
This paper marks a pivotal first step in applying social choice theory to population genomics. By shifting the focus from "finding the best metric" to "aggregating the best rankings," the authors have provided a robust framework for high-precision genetic identification with minimal data requirements.