
Empowering the User: A Semi-Automated Privacy Self-Assessment Framework for Social Networks
Expert Systems With Applications
This paper introduces a privacy self-assessment framework for Online Social Networks (OSNs) that combines a circle-based privacy leakage metric with an active learning-based recommendation system. The system, validated on real Facebook data, alerts users when their privacy exposure exceeds a defined threshold and helps semi-automatically configure visibility settings for profile items.
TL;DR
Social network privacy is broken—not necessarily by technology, but by human exhaustion. This paper presents a framework that measures your actual privacy risk using a "circle-based" metric and uses Active Learning to predict your privacy preferences, allowing you to secure your profile by labeling just a handful of friends instead of hundreds.
The "Frustration Gap" in Social Privacy
We live in an era where a single "Like" or a GPS tag can reveal religion, sexual orientation, or even whether your home is currently empty. While platforms like Facebook offer granular controls, most users fall into two dangerous extremes:
- Visible-to-all: Maximum social reach, but maximum risk.
- Hidden-to-all: Maximum privacy, but zero social utility.
The authors argue that the middle ground—customizing visibility for every friend—is too "annoying and frustrating" for humans to handle. Furthermore, the standard "separation-based" policies (Friends vs. Friends of Friends) are too blunt to capture the nuances of real human relationships.
Methodology: The Math and the Machine
The framework operates on two interconnected pillars: Risk Measurement and Preference Prediction.
1. Circle-Based Privacy Score
Unlike previous models that treat "Friends" as a monolith, this framework calculates a response matrix where the visibility of a profile item is proportional to the actual number of friends allowed to see it.
The privacy score is a function of:
- Sensitivity (): How rare and sensitive is the information? (e.g., political views are more sensitive than age).
- Visibility (): To how many people is this information spreading within your specific social graph?
2. Active Learning for Policy Configuration
This is the "How" of the paper. Instead of asking you to categorize 500 friends, the system uses a Naive Bayes classifier integrated with Uncertainty Sampling.
- Step 1: The system picks the 5 friends for whom the algorithm is most "confused" about (Maximum Entropy).
- Step 2: The user labels these 5 as "Allow" or "Deny."
- Step 3: The model retrains and propagates these preferences to the rest of the list.
Results: Efficiency Meets Security
The researchers tested this on 185 Facebook volunteers (real-world ego-networks). The results were striking:
- Accuracy Convergence: With as few as 20 labeled friends, the Accuracy and F-Measure reached stable, high levels.
- The "Careless" vs. "Wise" User: The framework successfully distinguished between "wise" users (who keep scores low through active labeling) and "careless" users, providing quantitative alerts to those at risk.
- Scalability: The computational complexity is linear , meaning it can process millions of users efficiently. Using a 16-core system, a complete check for a large platform would take just a few minutes.
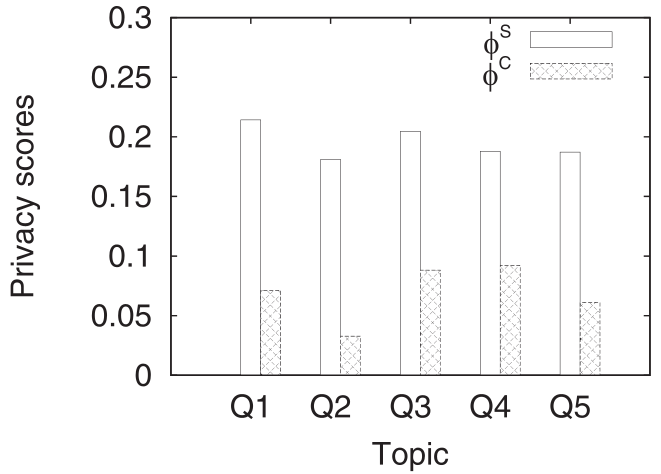 Figure: The Accuracy (left) and F-Measure (right) increase sharply as more friends are labeled, proving that active learning significantly reduces manual labor.
Critical Insight: Beyond Basic Attributes
The paper's "Circle-based" approach thrives because it focuses on where the information goes, not just what the information is. By integrating community detection (using the DEMON algorithm), the framework understands that your "Co-workers" circle has different privacy expectations than your "High School" circle, even if the individual friend attributes are sparse.
Conclusion and Future Outlook
This work shifts the burden of privacy from the user's patience to the machine's intelligence. While the model currently relies on profile attributes (age, location, etc.), the authors suggest that future versions could incorporate NLP and Sentiment Analysis to evaluate the sensitivity of actual posts and images automatically.
The takeaway for developers is clear: Privacy tools shouldn't just be available; they must be proactive.