
Teranga Go!: Quantifying Human Trust via Hesitant Fuzzy Linguistic Logic
A decision making model to evaluate the reputation in social networks using HFLTS
The paper introduces Teranga Go!, a carpooling social network that utilizes a Multi-Expert Multi-Criteria Decision Making (ME-MCDM) model to evaluate user reputation. It leverages Hesitant Fuzzy Linguistic Term Sets (HFLTS) and the 2-tuple linguistic model to transform subjective qualitative feedback into a definitive "Karma" score.
TL;DR
Trust is the ultimate currency of the sharing economy. Teranga Go! is a specialized carpooling social network that addresses the "stranger danger" problem by modeling user reputation as a Multi-Expert Multi-Criteria Decision Making (ME-MCDM) problem. By using Hesitant Fuzzy Linguistic Term Sets (HFLTS), it allows users to provide feedback in natural, "hesitant" language and converts it into a scientifically accurate "Karma" score.
Background: The Problem with Five-Star Ratings
In traditional sharing platforms, a 4.5-star rating often masks the complexity of human experience. Numerical systems force users to quantify feelings that are inherently qualitative and often uncertain. How do you distinguish between "I think they were good" and "I'm sure they were excellent"? Furthermore, simple averaging of scores often loses the "nuance" of the expert's confidence level.
Teranga Go! operates on the Computing with Words (CW) paradigm. It recognizes that our brains work better with perceptions than measurements. The core challenge addressed here is: How can we build a computational model that handles the same kind of uncertain, linguistic information that humans use?
Methodology: The Architecture of Reputation
The proposed model follows a sophisticated workflow to ensure that subjective opinions are processed without loss of information.
1. Linguistic Expression and Hesitation
Instead of a slider, users assess peers based on criteria (Cleanliness, Conversation, Security, Comfort) using a context-free grammar. This allows for expressions like:
- "Between Good and Very Good"
- "At least Normal"
2. The CW Scheme
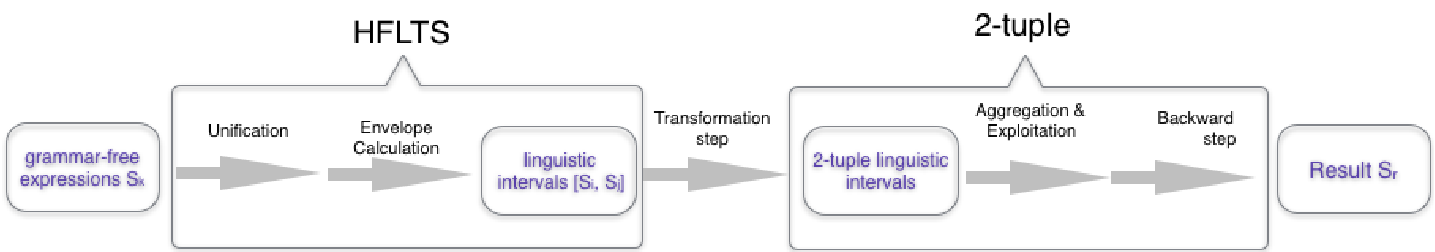
The system uses a 5-step process illustrated in the model's architecture:
- Unification: Converting various linguistic expressions into a uniform HFLTS set.
- Interval Calculation: Computing the "envelope" (the upper and lower bounds) of the hesitant terms.
- 2-Tuple Transformation: Representing these intervals as pairs , where is a linguistic term and is a symbolic translation value to maintain mathematical precision.
- Aggregation: Two rounds of weighted averaging—first for criteria (based on user journey preferences) and second for experts (weighted by their community experience).
- Exploitation: Converting the final fuzzy result back into a single human-readable word for the user's profile.
Deep Insight: Expert Weighting through Gamification
One standout feature of the Teranga Go! model is how it calculates Expert Weights. It uses a percentage parameter (base expertise).
- If , everyone’s opinion is equal.
- If , the system favors "power users" who have traveled more and provided more moderated feedback. This ensures that a newcomer's malicious review cannot easily destroy the reputation of a veteran driver.
Experimental Results: A Case Study
The paper presents a simulation involving four users: spring, summer, autumn, and winter. By collecting multiple trip assessments for user summer, the model processed qualitative inputs like "between normal and very good" and "very good."
| User | Criteria (Security) | Criteria (Comfort) | ... |
|---|---|---|---|
| Spring | Very Bad | Very Bad | ... |
| Winter | [Good, Very Good] | Normal | ... |
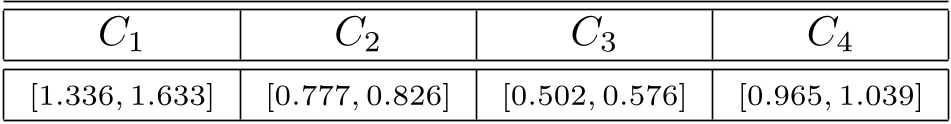
After two rounds of weighted 2-tuple aggregation, the "Karma" for summer was calculated as "Honest." This output is dynamic—as summer completes more trips, the system re-calculates the Karma, reflecting a living reputation.
Critical Analysis & Conclusion
Takeaway
Teranga Go! successfully demonstrates that Fuzzy Logic isn't just for industrial control systems; it's a powerful tool for social engineering. By bridging the gap between natural language and mathematical rigor, the authors provide a template for trust in the collaborative economy.
Limitations
- Complexity: The underlying math (2-tuple fuzzy sets) is complex to implement compared to simple averaging.
- Scalability: While effective for a carpooling community, the computational overhead of aggregating hesitant intervals at the scale of millions of users (like Uber or Airbnb) remains an open question.
Future Outlook
As decentralized platforms (Web3) grow, the need for "Objective Trust from Subjective Data" will become paramount. Integrating this HFLTS model with decentralized identity could be the next frontier in digital reputation.
For more details, you can visit the Teranga Go! open-source repository at GitHub.