
OntoILPER: Fusing Ontologies and Inductive Logic for Deep Relation Extraction
OntoILPER: an ontology- and inductive logic programming-based system to extract entities and relations from text
This paper introduces OntoILPER, an Ontology-based Information Extraction (OBIE) system that utilizes Inductive Logic Programming (ILP) to extract entities and relations from unstructured text. By integrating domain ontologies with the ProGolem learner, it achieves state-of-the-art results in Relation Extraction (RE) and competitive performance in Named Entity Recognition (NER) on the TREC corpus.
TL;DR
OntoILPER is a breakthrough in Ontology-Based Information Extraction (OBIE) that moves beyond the limitations of simple "feature vectors." By employing Inductive Logic Programming (ILP), it transforms sentences into rich relational graphs and induces human-readable Prolog rules to identify entities and the complex relationships between them. It doesn't just predict labels; it learns the underlying logic of the domain.
The Structural Bottleneck in Information Extraction
Standard machine learning models for Named Entity Recognition (NER) and Relation Extraction (RE) typically view text through the lens of propositional logic. They convert words into attribute-value pairs (vectors). However, language is inherently structural. A relationship like located_in(City, Country) isn't just about the words present; it's about the dependency path, the specific prepositional markers, and the ontological types of the participants.
The authors argue that existing systems fail because they lose this structural "essence" during the transformation to flat vectors. While kernel-based methods attempt to solve this via tree kernels, they often become a "black box" with thousands of sparse features.
Methodology: The Graph-Based Insight
OntoILPER's core innovation lies in its Relational Hypothesis Space. Instead of flattening data, it maintains a graph-based model of each sentence.
1. The Multi-Layer Graph
The system builds a representation that includes:
- Lexical Layers: Stems, lengths, and orthography.
- Syntactic Layers: POS tags and dependency parse trees.
- Structural Layers: Sequencing of tokens and "part-whole" chunk relationships.
2. Ontological Guidance
Unlike standard learners, OntoILPER is "guided" by a domain ontology. It uses the TBox (concepts and properties) to set the level of abstraction for its logic predicates. For example, it knows that the first argument of live_in must be a Person, focusing its search space significantly.
 Figure: The OntoILPER Architecture, showing the flow from text preprocessing to ontology population.
3. Rule Induction via ProGolem
The system uses the ProGolem learner to induce rules. These aren't opaque weights; they are actual Prolog clauses. A learned rule for a relation might look like:
located_in(A, B) :- t_ner(A, loc), t_next(A, B), t_ner(B, loc).
This provides explainability—a rare commodity in modern AI.
Experimental Performance: RE Dominance
The researchers tested OntoILPER on the TREC corpus, a benchmark for news-domain information extraction. The results showed a clear advantage in Relation Extraction.
Key Results:
- Superiority in RE: OntoILPER outperformed competitive baselines like Card-Pyramid parsing and Barrier Feature models. For the
work_forrelation, it achieved an F1 score of 83.8%, significantly higher than the joint-inference baseline of 61.4%. - Precision Power: In NER tasks, OntoILPER exhibited remarkably high precision, often exceeding 95%. This makes it ideal for industrial applications where "false positives" carry a high cost (e.g., populating a corporate knowledge base).
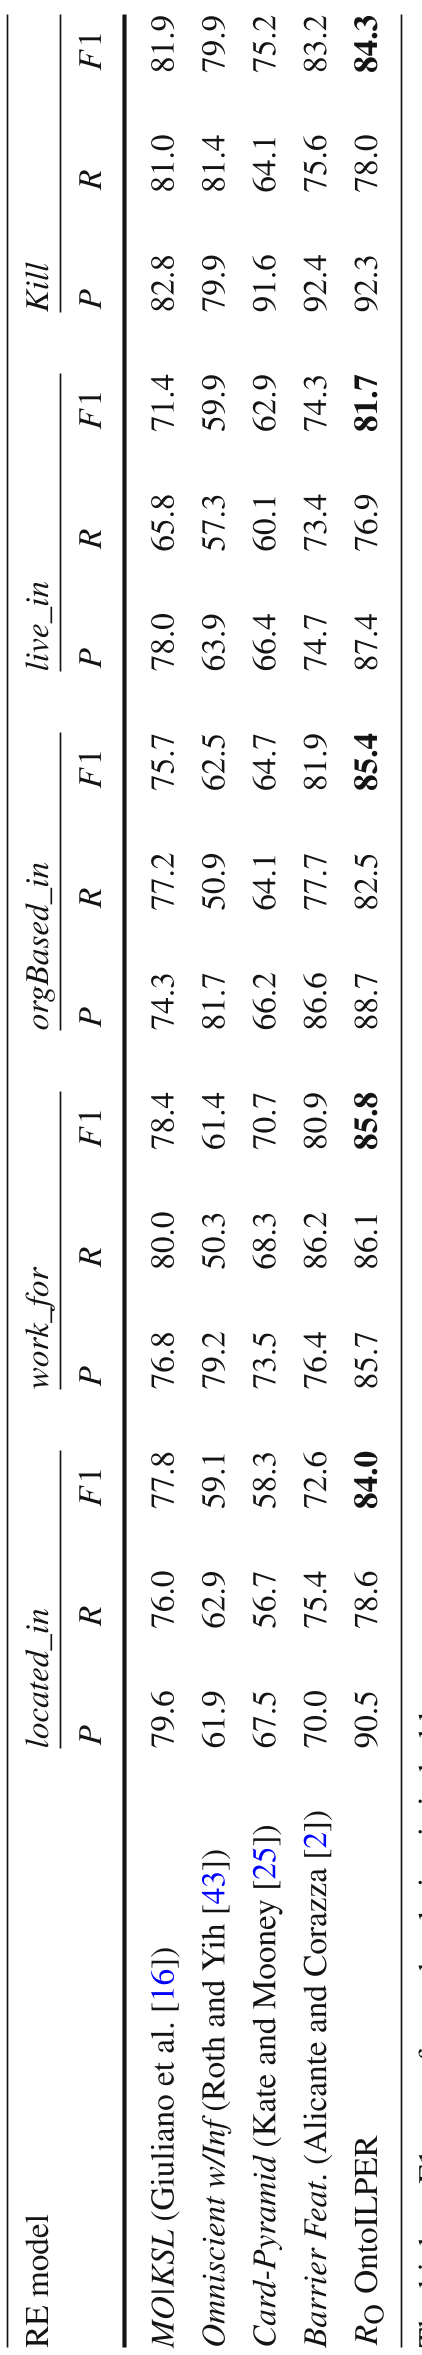 Table: Comparative evaluation showing OntoILPER's outperformance in Relation Extraction (RE).
Critical Insight: Why Symbolic Rules Win
The success of OntoILPER underscores a fundamental truth in Technical AI: Inductive Bias matters. By forcing the model to learn in a first-order logic space, the authors provided the model with the "grammar" of relations.
The Pipeline Model strategy described in the paper—where the system first learns to identify entities and then uses those learned rules as background knowledge for relations—creates a recursive learning loop that mimics human linguistic reasoning.
Conclusion and Future Directions
OntoILPER represents a significant step for Neuro-Symbolic approaches (even if focused on the symbolic side here). It proves that logical programs are not just artifacts of the past; they are powerful tools for managing the ambiguity of natural language.
Wait, what about Deep Learning? While the paper focuses on symbolic ILP, the authors acknowledge that future work could integrate WordNet hypernyms and deeper semantic role labeling. In today's context, the "Next Step" for this research is clear: combining the structural reasoning of OntoILPER with the massive latent knowledge of Large Language Models (LLMs) to create truly robust, explainable IE systems.