
Friendsourcing: Leveraging Social Trust for High-Precision Recommender Systems
Recommendations Given from Socially-Connected People
This paper introduces a "friendsourcing" recommendation algorithm that leverages explicit friendship connections within a social network to generate personalized suggestions. By combining structural similarity, behavioral rating patterns, and qualitative evaluation consensus, the method achieves localized, high-trust recommendations, integrated into a real-world healthcare social network for the QHIR LACCIR project.
TL;DR
This research moves away from the "anonymous crowd" of traditional Collaborative Filtering, proposing a Friendsourcing algorithm that prioritizes evaluations from a user's direct social circle. By quantifying similarity through friendship networks, rating behaviors, and activity levels, the system provides highly personalized and trustworthy recommendations, specifically validated within a healthcare social network.
Problem & Motivation
Most modern recommender systems (like those on Amazon or Netflix) operate on the principle of the "Wisdom of the Crowds." While effective for general consumer goods, this approach falters when trust and specific quality standards are paramount.
The authors identify a critical gap: Prior work often treats all "similar" users equally, regardless of their social proximity to the recipient. In a specialized environment—such as a medical network for university healthcare—a recommendation from a trusted colleague or friend carries significantly more weight than one from a mathematically similar stranger. The challenge lies in mathematically modeling this "social trust" without losing the predictive power of traditional Collaborative Filtering.
Methodology: The Core Triad of Similarity
The algorithm's genius lies in its composite similarity function, which goes beyond simple item-intersection. It calculates the similarity between a current user and a friend using three distinct pillars:
- Structural Similarity (): Measures the overlap in friendship circles. The intuition is that having many mutual friends implies a shared social context.
- Evaluative Similarity (): Quantifies how similarly two users rate specific quality attributes (e.g., trustworthy, objective, complete, well-written). It doesn't just look at what they liked, but why they liked it.
- Active Similarity (): Correlates the volume of ratings. A friend who is frequently active is deemed more "trustworthy" in their data footprint than a sporadic rater.
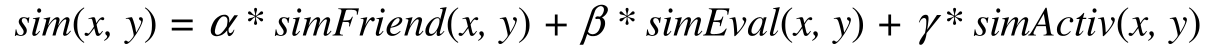
The Recommendation Pipeline
The system follows a filtered approach:
- Graph Traversal: Identify direct friends.
- Weighting: Apply weights () to the similarity components based on system goals.
- Quality Threshold: Only items meeting a "value of acceptance" based on weighted quality attributes are recommended.
Experiments & Results
The authors conducted individual component tests to verify the "Inductive Bias" of each similarity metric. Using standard IR metrics (Precision and Recall), they found that all three components positively contributed to recommendation accuracy.
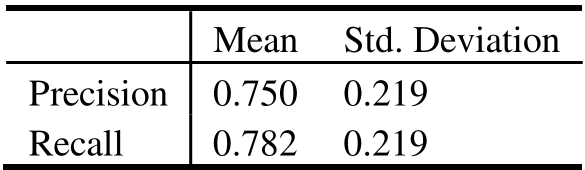 Table showing High Precision (0.75) for the Activity-based similarity component.
Key Findings:
- Activity Matters: Users with similar rating frequencies tended to provide the most reliable benchmarks for each other (Precision: 0.75).
- The Power of Shared Circles: Even without looking at item ratings, simply knowing a friend shares mutual connections () yielded a respectable Precision of 0.65.
Critical Analysis & Conclusion
Takeaway
The paper successfully demonstrates that Social Context is a proxy for Trust. By decomposing similarity into structural, evaluative, and behavioral components, the authors provide a framework that is more transparent and "human-centric" than standard black-box CF algorithms.
Limitations & Future Work
- Sparsity: The algorithm currently focuses on direct friends (first-level nodes). In small networks, this might lead to "cold start" problems where not enough items have been rated by one's immediate circle.
- Scalability: While tested on 50 users, the computational cost of re-calculating multi-attribute similarity across large-scale social graphs remains a question.
- Demographics: The authors correctly point out that future iterations should include demographic data (age, profession) to complement the graph-based metrics.
In conclusion, this work provides a vital blueprint for localized recommendation engines where the quality of the source is just as important as the content of the recommendation.