
Scaling Bot Detection: A Semi-Automatic Strategy for Military Info-Ops
A Semi-automatic Approach for Labeling Large Amounts of Automated and Non-automated Social Media User Accounts
The paper introduces a semi-automatic labeling framework to identify automated social media accounts (bots) specifically within the context of military information operations. By applying this method to 13,000 accounts involved in the Russia-Ukraine conflict, the researchers trained a Random Forest classifier that achieves a high precision of 0.98 on manually verified data.
TL;DR
Researchers from KTH and the Swedish Defence Research Agency (FOI) have developed a method to bypass the "bottleneck" of manual data labeling in bot detection. By using a semi-automatic approach based on behavioral "cut-offs," they successfully identified automated accounts in the Russia-Ukraine conflict with a precision of 98%, proving that models can generalize effectively even without expensive human-labeled datasets.
Problem: The Annotation Bottleneck
Detecting bots—automated accounts used for spam or psychological operations—usually requires thousands of manually labeled examples. This approach has three fatal flaws:
- Scale: Humans cannot keep up with the millions of accounts active in modern conflicts.
- Domain Shift: A "spam bot" behaves differently than a "military propaganda bot." Manual rules for one don't apply to the other.
- Evolution: Bot developers change their tactics constantly, making old training data obsolete.
The authors argue that we need a way to label data algorithmically yet reliably.
Methodology: The Power of Heuristic Pseudo-Labeling
The core innovation is a semi-automatic pipeline. Instead of a human looking at every account, the researchers used a set of "hard criteria" to create an initial labeled set.
1. The Multi-Feature "Cut-off"
They identified several features that, if high enough, almost certainly point to automation:
- Twitter-specific: Mention ratios (MTR), Hashtag ratios (HTR), and Duplicate URL ratios (DUR).
- General Behavioral: Timing uniformity (Pearson’s Chi-Square) and entropy-based regularity (Rao's Spacing).
If an account exceeded a conservative threshold in these metrics, it was labeled "Automated."
2. Generalization via Random Forest
The logic is brilliant in its simplicity: use these simple "rules" to label 13,000 accounts, then train a Random Forest classifier on that data. Because the Random Forest looks at all features simultaneously, it learns the nuanced relationships that simple rules miss.
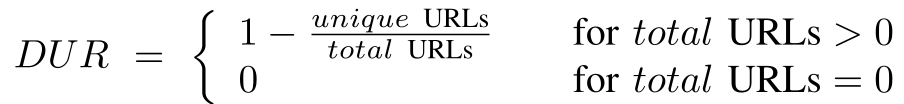 Example: The Duplicate URL Ratio (DUR) allows the system to catch accounts fixated on driving traffic to specific propaganda sites.
Experiments: Real-World Performance in the Ukraine Conflict
The model was tested on a dataset of 4 million tweets from the 2014 Russia-Ukraine conflict.
Key Results:
- Initial Test: 97.4% Precision on the semi-auto test set.
- The "Generalization" Proof: When the human researchers looked at the "False Positives" (accounts the model called bots, but the rules didn't), they found that 85% of them were actually bots. The model had successfully learned to "outsmart" the rules that created it.
- Human Verification: A manual audit of 50 predicted bots yielded a 0.98 precision rate.
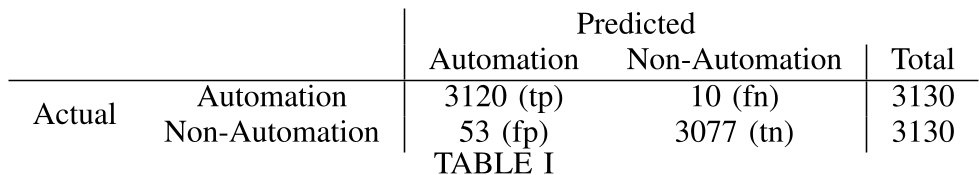 The model shows highly consistent behavior between training and predicted outcomes.
Critical Insight: Precision Over Recall
In the context of military information operations, Precision is king. While the model's recall was lower (0.38 in some manual tests), meaning it missed many bots, the accounts it did flag were almost certainly automated. For defense agencies, a low false-alarm rate is critical to maintaining the credibility of their analysis.
Conclusion
This paper demonstrates that we don't need "perfect" data to build a "highly effective" model. By leveraging simple behavioral statistics to bootstrap a machine learning classifier, researchers can respond to new information threats in days rather than months.
Future Outlook: The next step is real-time classification. As botnets become more sophisticated (using LLMs to mimic human text), these behavioral and temporal "fingerprints" (like timing entropy) may become the only reliable way to distinguish between a human and a machine.