
Scaling Affective Intuition: Distributed ELM and Statistical Learning for Big Social Data
16380_Statistical Learning Theory and ELM for Big Social Data Analysis.
This paper introduces a distributed implementation of Extreme Learning Machines (ELM) using the Apache Spark framework tailored for Big Social Data analysis. The core contribution is the integration of Statistical Learning Theory (SLT) to automate hyperparameter selection and performance assessment, achieving state-of-the-art results in affective analogical reasoning (emotion and polarity detection).
TL;DR
The explosion of social data demands learning models that are both computationally efficient and statistically rigorous. This paper proposes a distributed Extreme Learning Machine (ELM) framework built on Apache Spark. By moving from matrix pseudo-inversion to Stochastic Gradient Descent (SGD) and utilizing Statistical Learning Theory (SLT) for automated model selection, the authors provide a scalable pipeline for high-accuracy sentiment and emotion recognition.
The Scalability Wall in Opinion Mining
In the era of "Big Social Data," we are no longer just analyzing text; we are mapping the human "Affective Space." Prior works using back-propagation neural networks suffer from slow convergence and local minima. While ELM offers a faster alternative by using random hidden weights, its reliance on the Moore-Penrose pseudo-inverse creates a memory bottleneck that prevents easy parallelization across clusters.
Furthermore, the "Big Data myth"—the belief that more data automatically equals better models—often leads to overfitting. The authors argue that we need more than just "more data"; we need rigorous uncertainty quantification.
Methodology: High-Performance ELM on Spark
The authors bridge the gap between theoretical ELM and practical Big Data engineering through two primary innovations:
1. The SGD Reformulation
To make ELM "Spark-native," the training is reframed as a convex optimization problem. Instead of a single matrix operation, they utilize Algorithm 1 & 2 (SGD for ELM), which allows Spark to perform iterative Map-Reduce operations.
- Memory Optimization: If the hidden layer size is small, the activation matrix is precomputed and cached.
- Computation Trade-off: If is large, the projection is computed online to save RAM at the cost of CPU cycles.
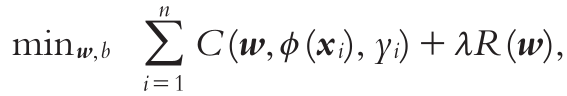
2. Theoretical Model Selection (SLT)
Rather than traditional (and expensive) -fold cross-validation, the paper introduces In-Sample methods based on:
- Rademacher Complexity (RC): Measuring how well the model can fit random noise.
- Algorithmic Stability (AS): Assessing how much the model output changes when one sample is removed.
- Bag of Little Bootstraps (BLB): A sub-linear resampling technique that maintains statistical integrity while significantly reducing the number of models to be trained.
Experimental Insights: AffectiveSpace 2
The framework was tested on the AffectiveSpace benchmarks—a vector representation of common-sense concepts linked to emotions like 'joy' or 'fear'.
Performance Comparison
The results prove that AffectiveSpace 2 (refined projection) significantly outperforms its predecessor. More importantly, the Bag of Little Hypothesis Stabilities (BLHS) method emerged as the superior model selection strategy, selecting models with the lowest reference set error.
Table: MS Method Comparison (Pleasantness Task)
| Loss Function | BLB Error | SRC Error | SUS Error | BLHS Error |
|---|---|---|---|---|
| L3 (Hinge) | 3.11 ± 0.10 | 3.46 ± 0.11 | 3.47 ± 0.11 | 2.74 ± 0.09 |
Scaling Efficiency
The paper provides a critical look at the "Next Iteration" time. As hidden neurons () increase, the "Online Projection" strategy (Algorithm 3) becomes significantly more efficient than Algorithm 2, which eventually triggers disk swapping.
Critical Analysis & Conclusion
This work successfully demonstrates that ELMs are not just "toy" models but powerful tools for Big Data when implemented correctly.
Key Contributions:
- Automated Hyperparameter Tuning: Using SLT bounds removes the "guesswork" and manual tuning usually associated with ELM.
- Distributed Flexibility: The Spark implementation adapts its strategy based on the available RAM and model complexity.
Limitations & Future Work: While powerful, the current approach is purely supervised. The authors suggest that the next frontier is Semi-Supervised Learning, leveraging the massive amount of unlabeled social data to further refine the "Affective Space."
Takeaway: If you are dealing with massive concept-level sentiment analysis, look past standard back-prop and consider the efficiency of a distributed, stability-governed ELM.