
Trust without Instinct: How Dynamic Networks Solve the Stag Hunt
Trust, Risk, and the Social Contract
This paper explores the evolution of cooperation through the lens of the Stag Hunt game, challenging the traditional view that "risk-dominant" non-cooperation is the inevitable long-run equilibrium. By introducing a dynamic social network model based on reinforcement learning, the author demonstrates how payoff-dominant cooperation can emerge and persist without assuming an innate biological predisposition to trust.
TL;DR
In the study of "Trust, Risk, and the Social Contract," Brian Skyrms argues that the emergence of human cooperation doesn't require us to be "born to trust." By moving from static interaction models to dynamic social networks where individuals learn who to talk to, cooperation (Stag Hunting) becomes the natural evolutionary winner over safe but lonely defection (Hare Hunting).
The "Risk Dominance" Trap
The central dilemma of social life is often modeled as the Stag Hunt. Two neighbors can coordinate to drain a meadow (Stag) for a high reward, but if one fails to show up, the one who tried loses everything. The alternative is to hunt a hare—a safe, solitary task with a lower but guaranteed reward.
In traditional evolutionary game theory, the "Hare" strategy is Risk Dominant. If you aren't sure what your neighbor will do, the risk of a zero payoff makes Hare the "rational" choice. Standard models suggest that even a population of cooperators will eventually collapse into defectors due to random mutations and the sheer safety of the Hare strategy.
Why Previous Models Failed
Early attempts to fix this, such as placing agents on a fixed circle or grid, actually made the problem worse. In a static local interaction model, a small cluster of "Hare hunters" can act like a virus, causing their "Stag hunting" neighbors to switch strategies because they can't avoid being let down.
The missing variable? Environmental Agency.
Methodology: The "Learning-to-Network" Paradigm
Skyrms introduces a co-evolutionary approach. Agents don't just change their strategy (how to play); they change their structure (with whom to play).
1. Structure as a Dynamic Entity
Instead of being forced to interact with a neighbor, agents use simple Reinforcement Learning (Roth & Erev, 1995). They keep a mental tally of who gave them a good payoff in the past.
2. The Feedback Loop
If I hunt a Stag with you and we succeed, my probability of picking you again increases. Soon, Stag hunters form "islands of cooperation."
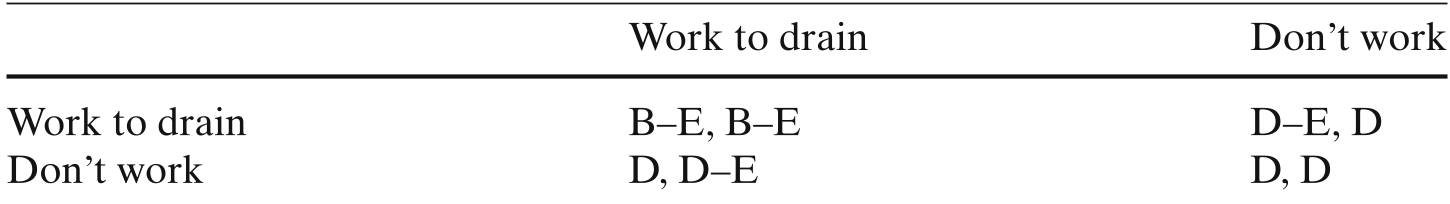
As the matrix shows, once Stag hunters find each other, their payoff becomes B-E (4), consistently outperforming the Hare hunters' D (3).
Experimental Insight: From Local to Global
The paper posits a hierarchical evolutionary process:
- Within Groups (Demes): Fast reinforcement learning allows Stag hunters to find each other, neutralizing the "risk" of being abandoned.
- Across Groups: Once a group becomes a "Stag hunting powerhouse," it becomes more attractive. Through mobility—moving from a Hare-dominated group to a Stag-dominated one—the cooperative strategy spreads across the entire population.
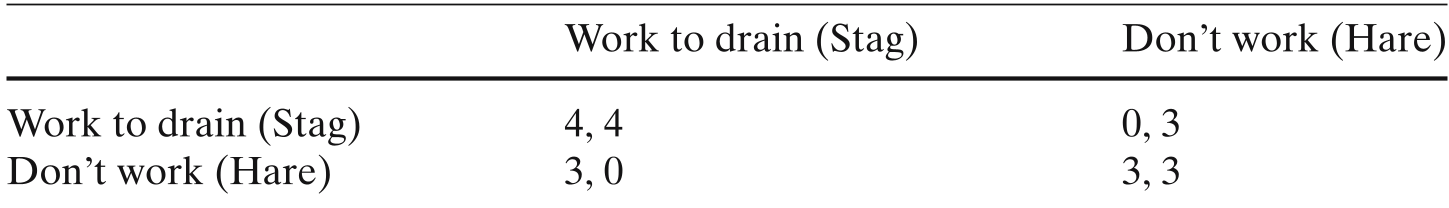
In this payoff structure, once the interaction is narrowed to the top-left cell (4,4), the risk-dominance of (3,3) vanishes.
Critical Analysis & Conclusion
The Takeaway
The genius of Skyrms' work lies in its minimalism. We don't need to be hyper-intelligent strategists or biologically programmed for altruism. We only need the ability to remember who was a good partner and the freedom to associate with them again.
Limitations
A potential hurdle is the "Search Cost" or "Fluidity" of the network. If the social structure is too rigid (legal barriers, geographic isolation), the "islands of cooperation" can never form, and we remain trapped in the Hare-hunting equilibrium.
Future Outlook
This work transcends philosophy and enters the realm of Network Science and AI. Modern decentralized systems (like blockchain or P2P networks) rely on similar principles of reputation and dynamic connection to foster "trust" in a trustless environment. The social contract, it seems, is less a formal agreement and more a successfully learned network topology.