
The Power of Averaged Confidence: Elevating Twitter Sentiment Analysis via Robust Ensembles
Twitter Sentiment Detection via Ensemble Classification Using Averaged Confidence Scores
The paper presents a high-performance ensemble classification system for Twitter sentiment detection (positive, negative, or neutral). By reproducing and combining three state-of-the-art models (NRC-Canada, GU-MLT-LT, and KLUE) using averaged confidence scores, the authors achieved a top-5 ranking performance on SemEval 2013 and 2014 datasets.
TL;DR
This research demonstrates that reproducing and combining diverse state-of-the-art sentiment classifiers into an ensemble can significantly boost performance. By specifically averaging confidence scores from three top-tier models (NRC-Canada, GU-MLT-LT, and KLUE), the authors built a system that would have ranked in the top 5 of 50 participants at SemEval 2013 and 2014, proving that simplicity in combination logic often triumphs over complex weighting schemes.
Background & Motivation: Why Twitter is Still Hard
Despite the evolution of NLP, Twitter remains a "wild west" for text processing. The 140-character limit (at the time of the paper) forces a density of slang, emoticons, and creative punctuation that standard linguistic tools struggle to parse.
The authors identified two major roadblocks in the field:
- Reproducibility Gap: Submission notebooks for shared tasks like SemEval are often too brief to allow for exact replication, making it hard to build upon previous "state-of-the-art" (SOTA).
- Component Limitations: No single feature set (N-grams, lexicons, or clusters) captures the full spectrum of human emotion expressed in tweets.
Methodology: Synergy through Diversity
Instead of building a new model from scratch, the authors selected three high-performing but structurally different systems to form an ensemble.
1. The Components
- NRC-Canada: A "feature-heavy" beast using N-grams, character-level features, and five distinct polarity dictionaries (some crawled from hashtags/emoticons).
- GU-MLT-LT: Focused on normalized unigrams and unsupervised Brown clustering to handle the vocabulary explosion of social media.
- KLUE: Utilized frequency-weighted N-grams and the AFINN-111 lexicon, with a specific focus on colloquial abbreviations.
2. The Secret Sauce: Averaging Confidences
The core insight of this paper is the move from "Hard Voting" (majority wins) to "Soft Voting" (averaging probabilities).
The authors observed that hard voting actually performed worse than the best individual model (NRC) in development. Why? Because the individual classifiers often failed on the same "hard" tweets. However, by averaging the probabilities (), a model that is very certain about a class can "overrule" two models that are only slightly leaning toward a different (incorrect) class.
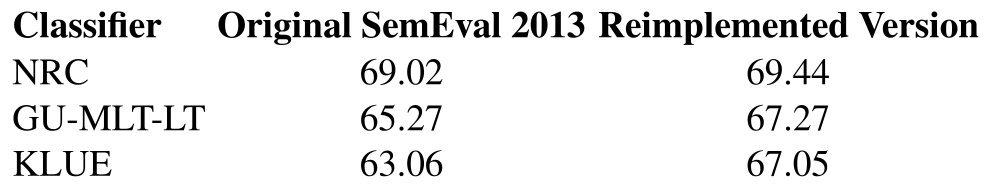
Experiments & Results
The authors didn't just reproduce the models; they improved them. By switching the learning algorithm to L2-regularized logistic regression (LIBLINEAR), they achieved higher scores than the original authors in two out of three cases.
Performance Metrics
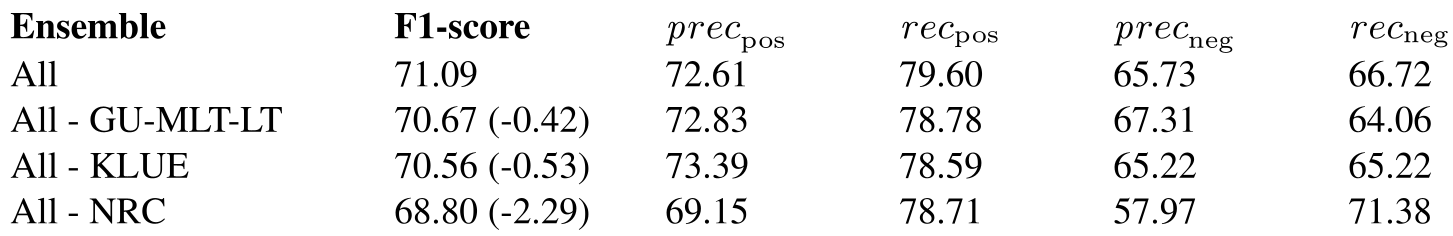
- SemEval 2013: The ensemble hit an F1-score of 71.09, effectively becoming the new benchmark by beating the original NRC system (69.02).
- SemEval 2014: It maintained a top-5 position, proving its robustness across years and shifting linguistic trends.
Error Analysis: The "Safe" Neutral
A critical finding was the ensemble's "failure mode." As shown in the confusion matrices, the system rarely committed "severe" errors (e.g., calling a negative tweet positive). Instead, most errors were "neutral" misclassifications. In a product or PR context, this is a highly desirable trait—it is better to be "unsure" (neutral) than "confidently wrong" about a customer's sentiment.
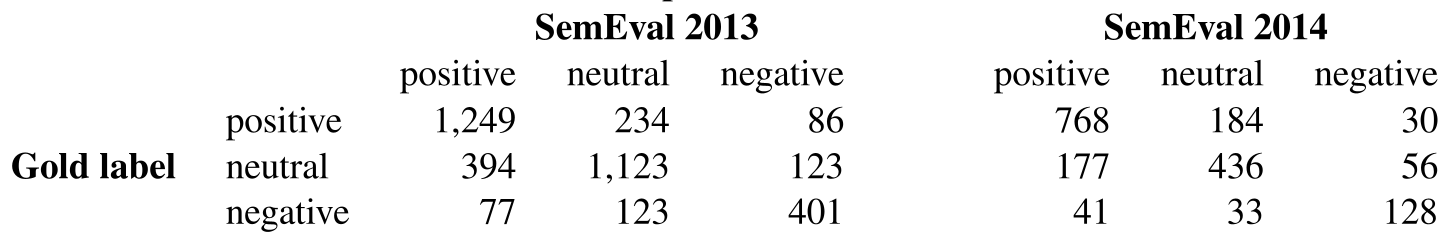
Critical Insight & Conclusion
This paper serves as a landmark study for Robust AI. It highlights that the "Ensemble Effect" isn't just about adding more models; it's about adding dissimilar models and choosing a combination strategy that preserves uncertainty.
Takeaways for Practitioners:
- Diversity is Key: Don't ensemble three models that use the same features. Combine a lexicon-based model with a cluster-based one.
- Confidence Matters: When building production classifiers, always export probabilities. Averaging these is a "cheap" but extremely effective way to boost accuracy without training a complex meta-classifier.
Limitations: The study relies on hand-crafted features which are now largely superseded by Transformer-based embeddings (like BERT). However, the logic of soft-voting ensembles remains a fundamental tool in the modern NLP engineer's toolkit.