
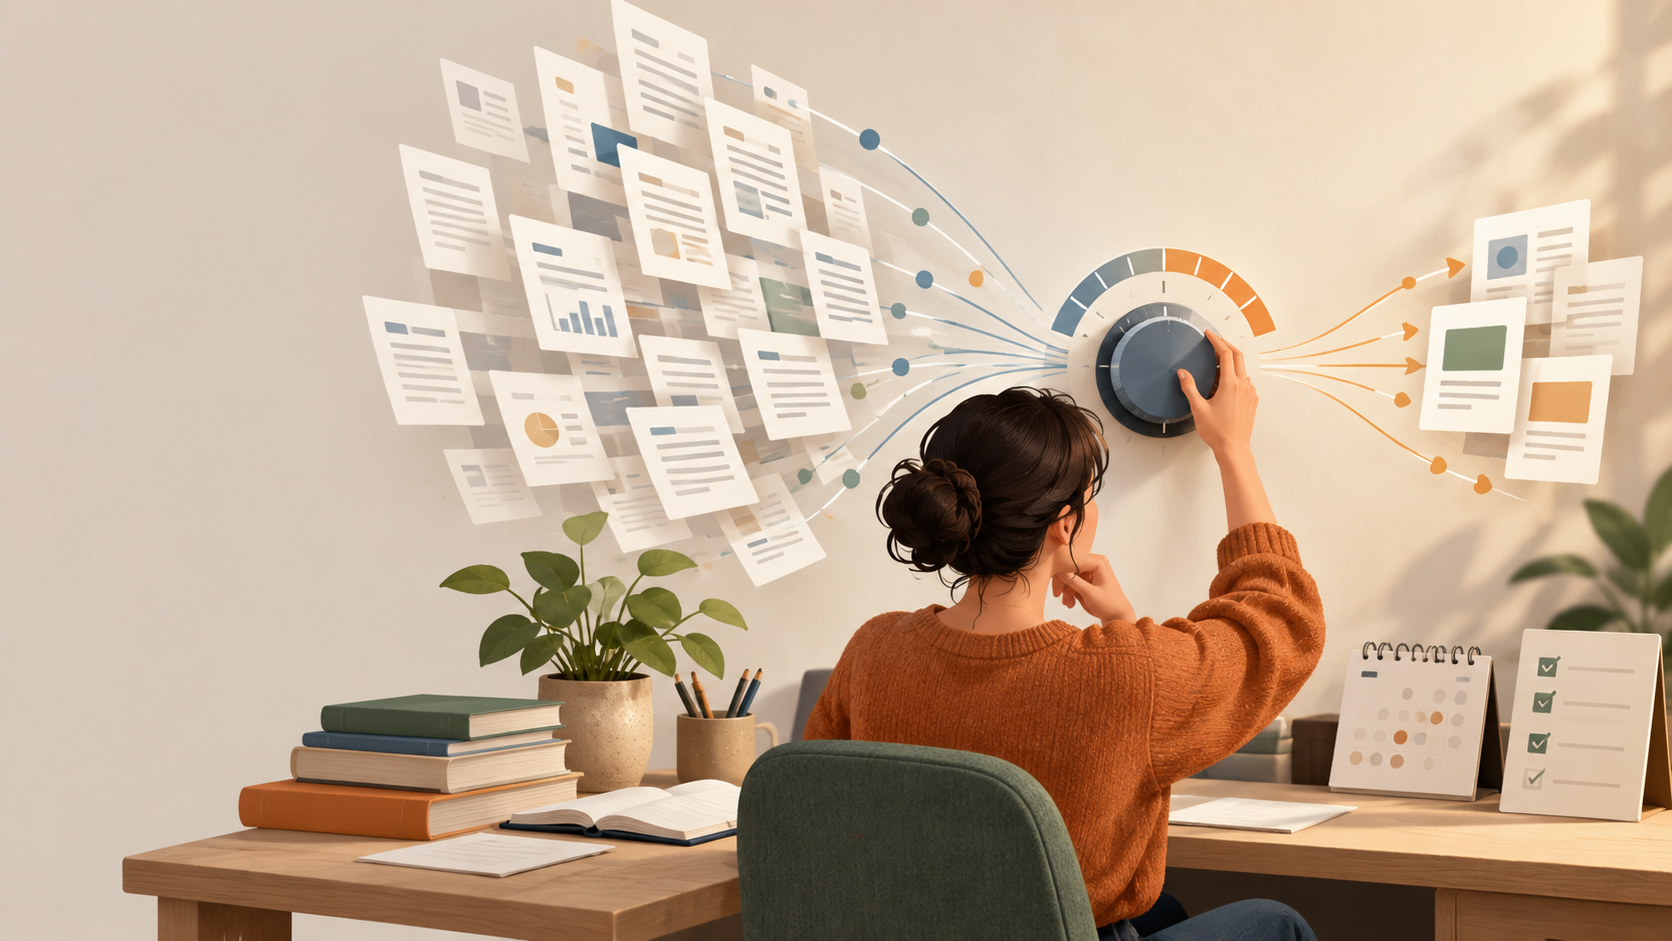
Under a deadline, the question is rarely "should I search broadly or narrowly?" It is "which move gets me to defensible evidence fastest?" Broad recall and narrow precision are not rival philosophies; they are two ends of one dial you turn as your task changes. The practical answer: start broad enough to see the field, narrow once your eligibility criteria are clear, and stop when new searches stop changing your evidence set.
This article compares four tactics on the same task — recall, precision, known-item testing, and staged narrowing with stop rules — shows where each fails, and gives a decision table plus a combined workflow. The running example is a student finishing a course paper under a tight deadline with a rubric that rewards a clearly justified evidence base.
The same task, four tactics
Imagine you have ten days to write a paper on a defined topic. Your rubric rewards a justified selection of sources, not sheer volume. You have limited full-text access and expect supervisor feedback partway through. Every tactic below is judged against that task: does it surface the evidence the rubric rewards, within the time and access you actually have?
- Recall-first search: cast wide to capture as many potentially relevant records as possible.
- Precision-first search: use tight terms and filters to return only close matches.
- Known-item testing: check whether specific papers you already trust can be retrieved.
- Staged narrowing with stop rules: broaden, then narrow in documented stages, and define in advance when to stop.
Recall: breadth as a coverage strategy
Recall-oriented searching tries to miss as little as possible. The Cochrane Handbook's guidance on searching for studies supports planning searches from explicit eligibility criteria, drawing on multiple sources, and combining free-text terms with subject headings. That combination is a recall tactic: free text catches new phrasing, subject headings catch indexed vocabulary, and multiple sources reduce dependence on any single index.
Where recall fails under a deadline: it produces volume you must screen. Cochrane's process includes deduplicating records and screening in stages precisely because broad searches generate many records. If you have limited access and a short window, an unbounded broad search can bury the few papers your rubric rewards. Recall is a coverage strategy, not a finishing strategy.
Precision: filters, fields, and the cost of tightness
Precision-oriented searching narrows what comes back. PubMed supports field tags, phrase searching, filters, and Advanced Search, and its search details show how terms were translated and combined. Google Scholar documents searching by author and title, date limits, and date sorting. These are precision tools: they let you target a field, a phrase, or a window.
Where precision fails: tighten too early and you exclude relevant work before you know the vocabulary of the field. A filter applied before you understand how authors phrase the topic can hide the very studies your rubric wants. Precision is most useful after you have seen enough records to know which terms and fields actually discriminate.
Known-item testing: a fast check on your search
Known-item testing asks a simple question: can my search retrieve papers I already know are relevant? Google Scholar's author and title search, and PubMed's citation lookup, both support finding a specific work you can name. If a search strategy cannot surface a paper you already trust, that is a signal to adjust terms or sources before you invest more time.
Where it fails: it only tests the items you already know. A strategy that retrieves your known papers can still miss adjacent work you have not encountered. Use known-item testing as a quick calibration step, not as proof of coverage.
Staged narrowing: the workflow the guidance actually describes
The strongest option for a deadline is staged narrowing. Cochrane's process is explicitly staged: plan from eligibility criteria, search multiple sources, deduplicate, screen in stages, and rerun searches before publication. That sequence is a template for turning a broad recall pass into a precise, defensible set.
A workable student version:
- Define eligibility first. Write the inclusion criteria your rubric implies before you search.
- Run a broad pass. Combine free-text and subject terms across more than one source.
- Deduplicate and screen in stages. Title/abstract first, then full text.
- Narrow with fields and filters once you know the field's vocabulary.
- Rerun before you submit to catch anything new.
For the search itself, you can run this in a scholarly search interface such as WisPaper search, and if you want a public entry point to finding academic papers, the WisPaper Scholar Search page explains that starting point. As you collect candidates, save and organize them in My Library so screening happens against one list rather than scattered tabs.
Stop rules: deciding when the search is done
A stop rule is a pre-committed condition for ending a search stage. Under a deadline, stop rules protect you from two failures: stopping too early on a thin evidence base, and searching forever.
Practical stop rules that fit the guidance:
- Saturation rule: stop broadening when a new source adds no new eligible records after a defined number of attempts.
- Known-item rule: stop adjusting terms when your trusted papers are retrievable and new terms no longer surface new candidates.
- Stage rule: do not narrow until title/abstract screening is complete; do not stop screening until full-text decisions are recorded.
- Rerun rule: schedule one final rerun before submission, as Cochrane recommends rerunning searches before publication.
Where stop rules fail: a stop rule set too loosely ends the search on a thin base; set too tightly, it keeps you searching past the point of new returns. Write the rule down before you start so the deadline, not fatigue, decides.
Where each tactic breaks: a comparison
| Tactic | Best for | Fails when | Deadline risk |
|---|---|---|---|
| Recall-first | Seeing the field; coverage | Screening volume exceeds time | High if unbounded |
| Precision-first | Targeting a known field or phrase | Vocabulary not yet known | Misses relevant work |
| Known-item testing | Calibrating a strategy | Treated as proof of coverage | False confidence |
| Staged narrowing + stop rules | Defensible evidence under time pressure | Rules not written in advance | Low if rules are explicit |
A decision table for your next search session
| Your situation | Start with | Then | Stop when |
|---|---|---|---|
| New topic, unclear vocabulary | Recall-first, multiple sources | Narrow with fields once terms emerge | New sources add no eligible records |
| You know key papers | Known-item test | Broaden to adjacent terms | Trusted papers retrieve and new terms plateau |
| Rubric rewards justified selection | Eligibility criteria first | Staged narrowing | Screening complete and rerun done |
| Limited full-text access | Precision on accessible sources | Known-item check for gaps | Accessible eligible set is stable |
| Supervisor feedback expected | Broad pass early | Narrow after feedback | Feedback addressed and rerun done |
Combined workflow for the deadline example
Back to the ten-day paper. Days 1–2: write eligibility criteria and run a broad pass across more than one source, combining free-text and subject terms. Days 3–4: deduplicate and screen titles/abstracts in stages, saving candidates in one library. Day 5: known-item test — can you retrieve the papers your supervisor named? If not, adjust terms. Days 6–7: narrow with field tags and filters now that you know the vocabulary. Day 8: full-text screening and a first rerun. Day 9: incorporate supervisor feedback and rerun again. Day 10: final rerun, then submit.
If your supervisor asks questions about the papers you have collected, you can pose them against your saved set using Library QA, which supports asking questions based on papers uploaded to My Library or added from search results. If the task grows into a longer literature review, Scholar Agent fits longer research tasks in its literature review, inspiration, or reproduction use cases. Before submission, if you are assembling a BibTeX file, TrueCite checks BibTeX against real academic databases to flag hallucinated references — a concrete final check that pairs with the rerun rule.
The submission decision
Submit when three conditions hold: your eligibility criteria are written and applied, your screening is complete through full text, and a final rerun produced no new eligible records. That is a defensible stopping point your rubric can see. If the rerun surfaces new eligible work, screen it and rerun once more; if it does not, submit.
FAQs
Keep Reading
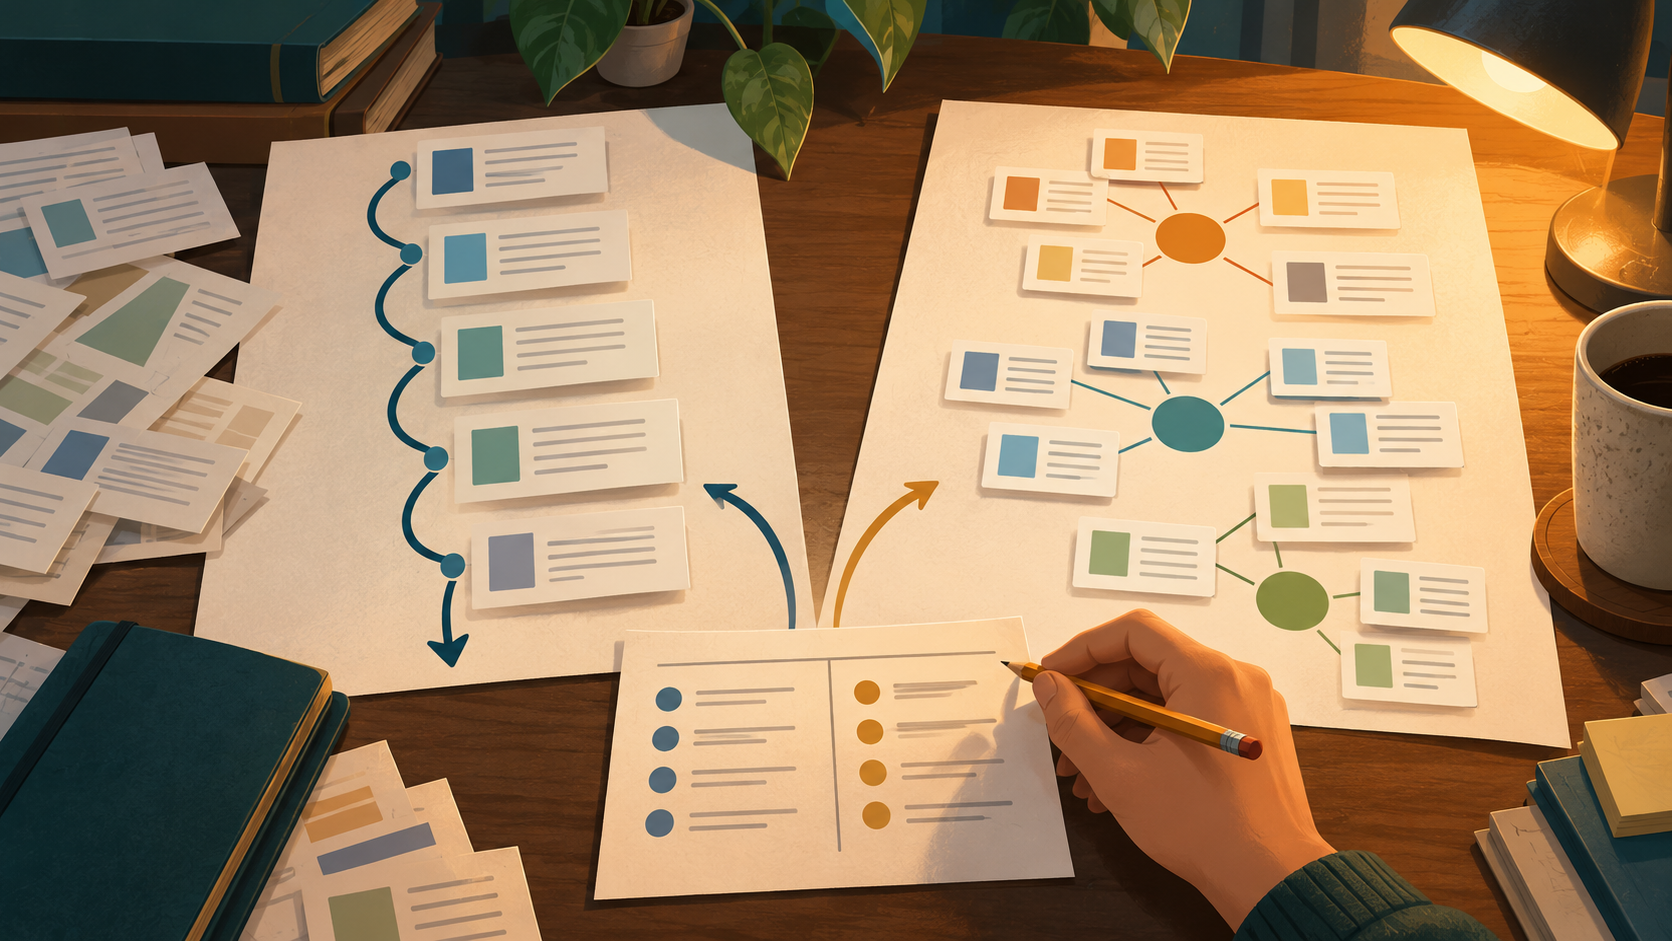
Chronological vs. Thematic Literature Review Structure: Choosing by Question and Evidence
A literature review can be organized in two common ways. A **chronological** structure follows how a field developed over time. A **thematic** (argument-centered) structure groups studies by the ideas, debates, or mechan
Citation Verification: A Complete Pre-Submission Workflow
Citation verification is the practice of confirming, for every reference in a manuscript, that the work exists, that its metadata is correct, that you are citing the right version, that its correction status is known, th
Crossref vs. PubMed Metadata: Why the Same Paper Can Look Different
A single paper can appear under slightly different titles, author strings, dates, and subject terms depending on whether you meet it through a publisher deposit or through PubMed. For a clinician or researcher building a